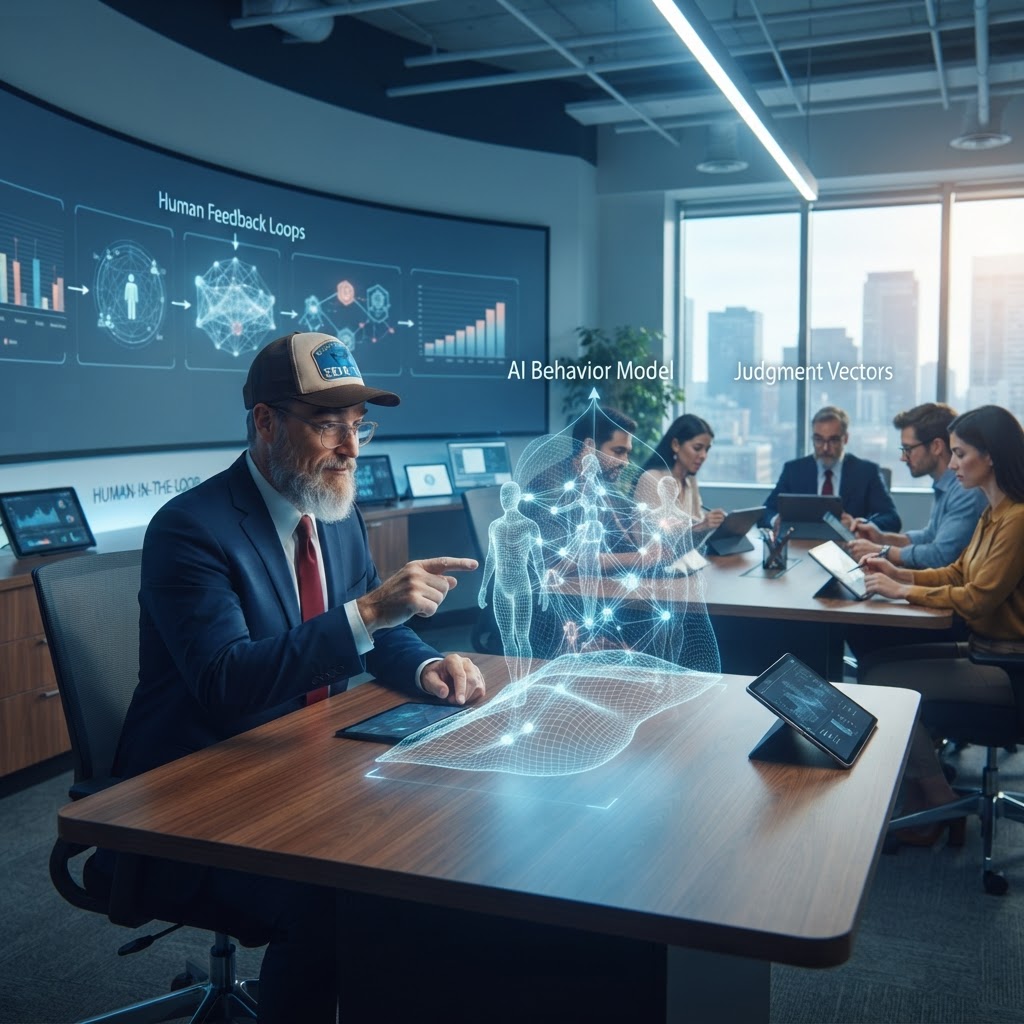
AI conversations increasingly use the word superintelligence. That can sound as if artificial intelligence has been renamed. It has not. AI is the broad field and the tools we use today; artificial superintelligence is a proposed level of capability beyond human performance across many cognitive tasks. The distinction matters when you are deciding what to build now.
How RLHF works
Reinforcement learning from human feedback, or RLHF, is one way to steer a language model toward responses people prefer. A model first learns patterns from large datasets. Trainers then provide examples of useful answers. For the same prompt, the model produces alternatives and human reviewers compare them. A reward model learns to predict those preferences; the language model is tuned to score better against that signal. OpenAI describes this sequence in its InstructGPT work.
Imagine an assistant asked to summarize a customer issue. One answer may sound polished but omit the actual problem. Another may name the problem, distinguish confirmed facts from guesses, and suggest a next step. Human reviewers can prefer the second. Repeated comparisons help shape the model's behavior. They do not make every later answer correct.
Why feedback is only part of the system
A reward model learns from the people, prompts, and criteria used in training. It can inherit blind spots, reward confident wording over evidence, or perform poorly outside familiar tasks. OpenAI has explicitly described the limitation: human feedback assumes people can evaluate the model's work accurately. More capable systems may produce work that takes specialized knowledge or extensive checking to judge.
That is why a founder should treat AI behavior as one layer of a business system. Define the task, connect trustworthy information, test the output, and make consequential actions reviewable. If the assistant drafts a proposal, someone still checks the promise, price, and scope before it reaches a client.
Where the future may go
Researchers are exploring AI-generated feedback, preference optimization methods, stronger evaluations, and ways for people to supervise work they cannot fully inspect alone. Google DeepMind's 2026 discussion of a path from AGI to ASI describes possible routes, not a declaration that superintelligence has arrived. The timing and shape of that future remain uncertain.
A practical approach is simpler: the valuable systems will make intelligence accountable. They will show what information was used, where uncertainty remains, who can approve an action, and whether the result solved the real problem. If you are building with AI today, start with one workflow and a clear definition of a good outcome. Human judgment is still part of the product.
Have a workflow that needs more than another prompt? Explore building with Scott.
Further reading
OpenAI's InstructGPT explanation of RLHF; OpenAI on human feedback and its limits; Google DeepMind's research on paths from AGI to ASI.